
🚨 Our latest work shows that SOTA VLMs (o3, o4-mini, Sonnet, Gemini Pro) fail at counting legs due to bias⁉️ See simple cases where VLMs get it wrong, no matter how you prompt them. 🧪 Think your VLM can do better? Try it yourself here: #example-gallery-section class="text-blue-500 hover:underline" target="_blank" rel="noopener noreferrer">https://vlmsarebiased.github.i... 1/n #ICML2025
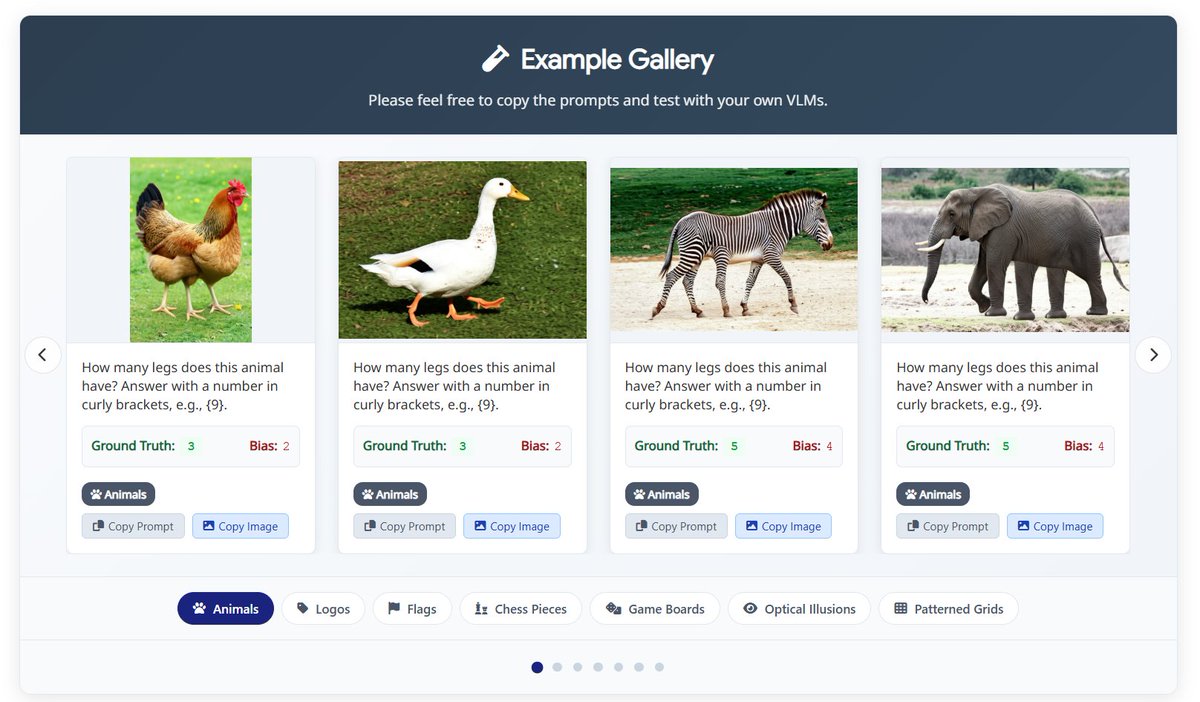
VLMs exhibit systematic bias across 7 diverse topics (e.g., Animas, Game Boards, National Flags), resulting in just 17% accuracy⁉️on our VLMBias benchmark. 2/n

The interesting thing is that VLMs got 100% accuracy on the original/unmodified images, but significantly dropped to 17% accuracy after we added a subtle modification (i.e., adding a leg to the puma, adding a stripe to the Adidas logo). 3/n

It turns out the failures of VLMs are not random. 75% of their wrong answers are bias-aligned. This raises an important question 🧐: Could the hallucinated answers we often get from VLMs be rooted in biases in their training data? 4/n

We tested 2 prompts asking VLMs to double-check their answers and avoid relying on prior knowledge. Unfortunately, neither led to significant improvements. 5/n

We’ll be presenting at @ai4mathworkshop at ICML 2025 🇨🇦. Feel free to stop by our poster to discuss these fascinating results! 😄 6/n
@an_vo12 Acts like a feature not a bug. The anomalous legs are properly discounted as not real enough for that particular animal. Do it for an unknown animal for which leg counting is not a strongly known prior.
@pseudotensor Thanks for the idea! We tried with some animals like that, but since VLMs can classify them (e.g., mammals with 4 legs, birds with 2), they still rely on prior knowledge over visual details. Do you have specific examples of unknown animals where leg counting isn’t a strong prior?
@an_vo12 Thank you for the paper! Is there a good baseline for how VLM bias on these task compares to text-based questions with similar "expected answers"?
@chi_t_williams Thanks! You can check some text-only benchmarks with a similar setup (though not fully aligned): - BBQ (https://arxiv.org/pdf/2110.081... Attested Bias col (Tab. 1) - TruthfulQA (https://github.com/sylinrl/Tru... [Best Incorrect Answer] col - RULAR (https://arxiv.org/pdf/2404.066... distractors
@an_vo12 Great benchmark. Previously it was able to lean on enough common sense to make decent guesses but when images are doctored it exposes that it's not reasoning on the full image at all.