
Let's build a reasoning LLM, from scratch (100% local):
Today, we're going to learn how to turn any model into a reasoning powerhouse. We'll do so without any labeled data or human intervention, using Reinforcement Finetuning (GRPO)! Tech stack: - @UnslothAI for efficient fine-tuning - @HuggingFace TRL to apply GRPO Let's go! 🚀
What is GRPO? Group Relative Policy Optimization is a reinforcement learning method that fine-tunes LLMs for math and reasoning tasks using deterministic reward functions, eliminating the need for labeled data. Here's a brief overview of GRPO before we jump into code:
1️⃣ Load the model We start by loading Qwen3-4B-Base and its tokenizer using Unsloth. You can use any other open-weight LLM here. Check this 👇

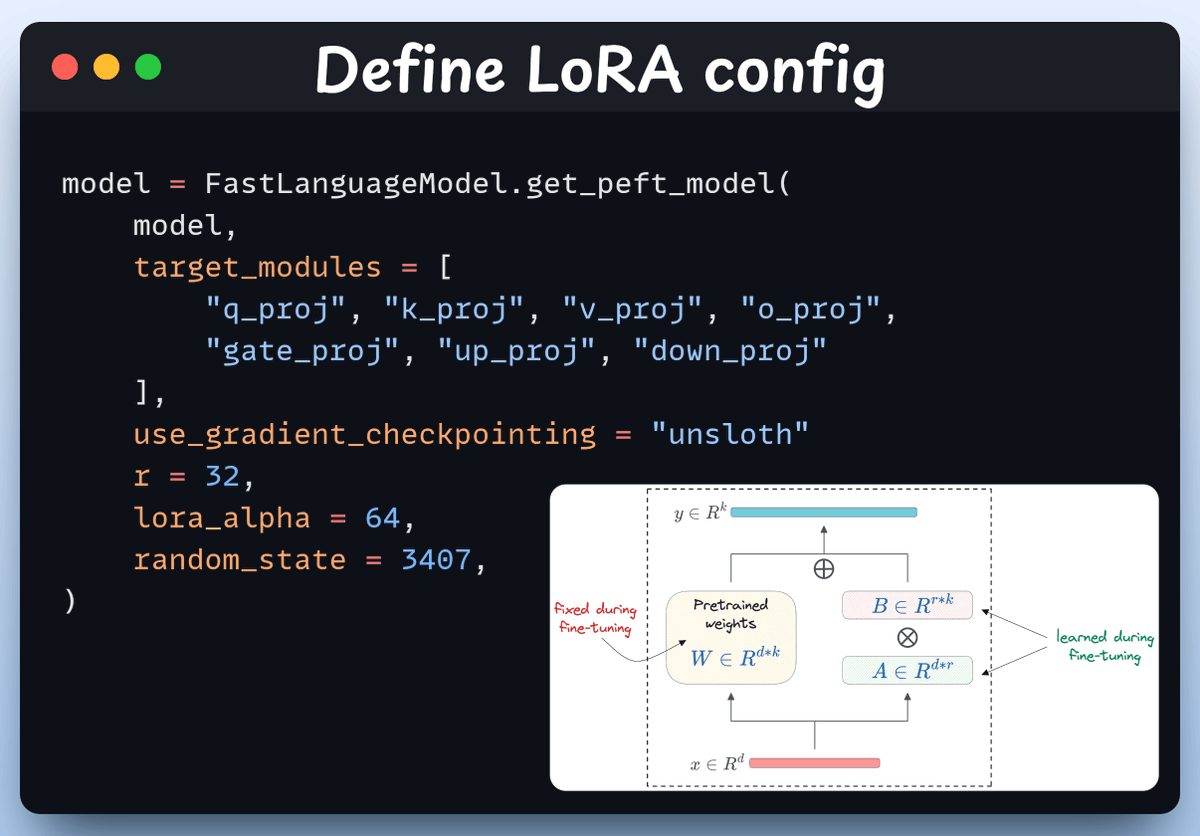
2️⃣ Define LoRA config We'll use LoRA to avoid fine-tuning the entire model weights. In this code, we use Unsloth's PEFT by specifying: - The model - LoRA low-rank (r) - Modules for fine-tuning, etc. Check this 👇
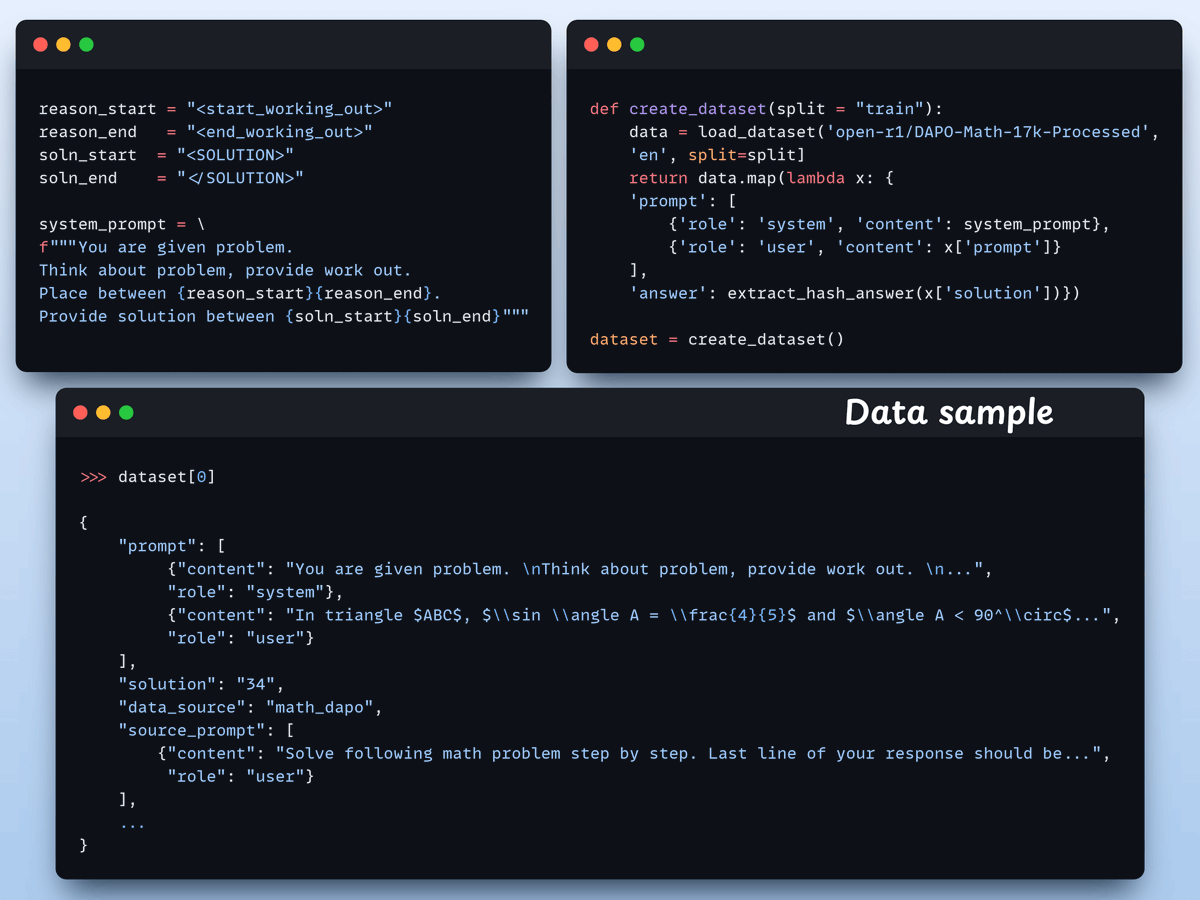
3️⃣ Create the dataset We load Open R1 Math dataset (a math problem dataset) and format it for reasoning. Each sample includes: - A system prompt enforcing structured reasoning - A question from the dataset - The answer in the required format Check this code 👇
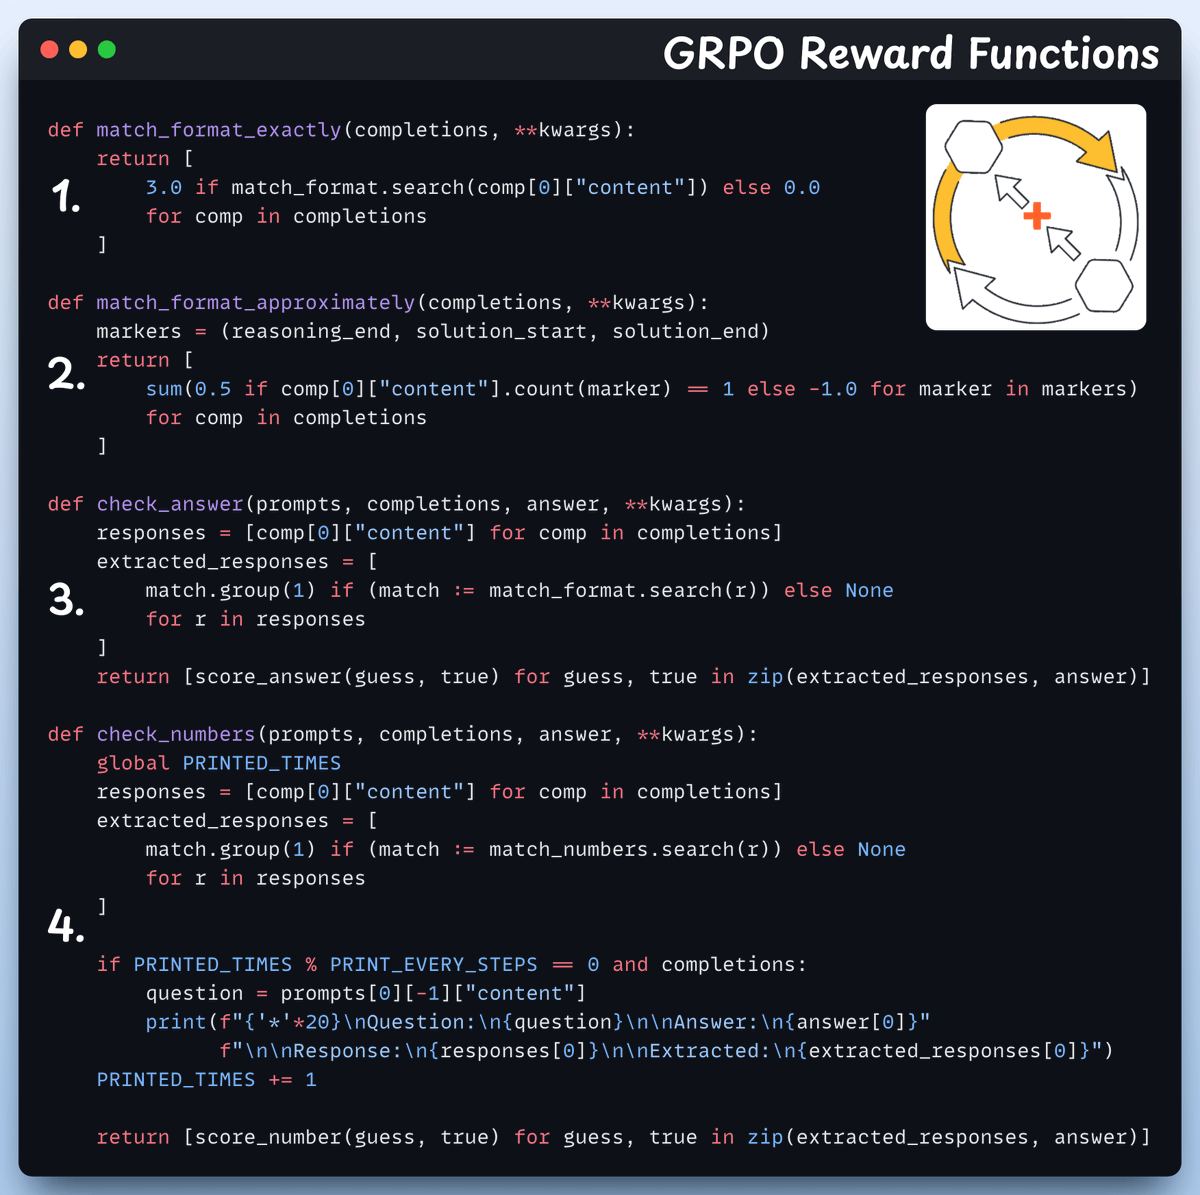
4️⃣ Define reward functions In GRPO we use deterministic functions to validate the response and assign a reward. No manual labelling required! The reward functions: - Match format exactly - Match format approximately - Check the answer - Check numbers Check this out 👇
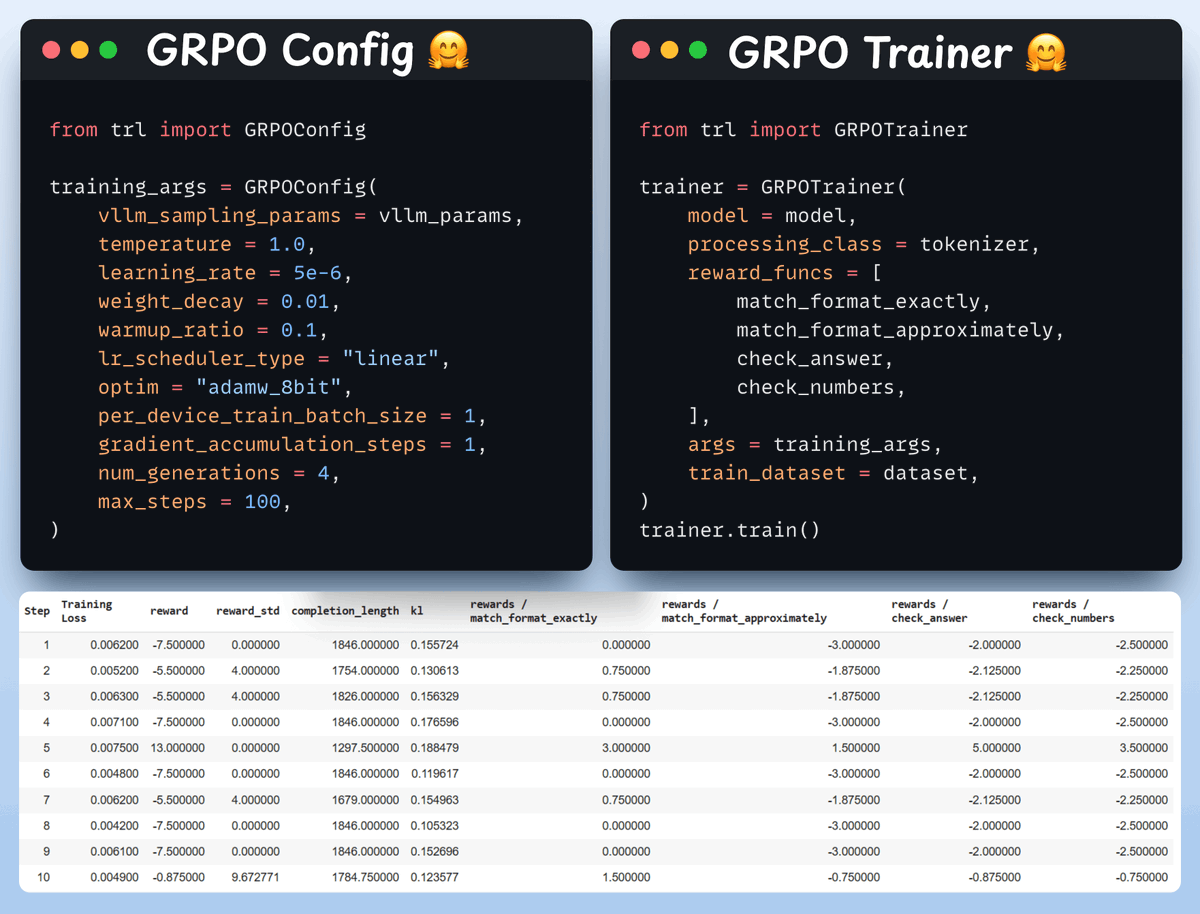
5️⃣ Use GRPO and start training Now that we have the dataset and reward functions ready, it's time to apply GRPO. HuggingFace TRL provides everything we described in the GRPO diagram, out of the box, in the form of the GRPOConfig and GRPOTrainer. Check this out👇
6️⃣ Comparison Again, we can see how GRPO turned a base model into a reasoning powerhouse. Check this out👇
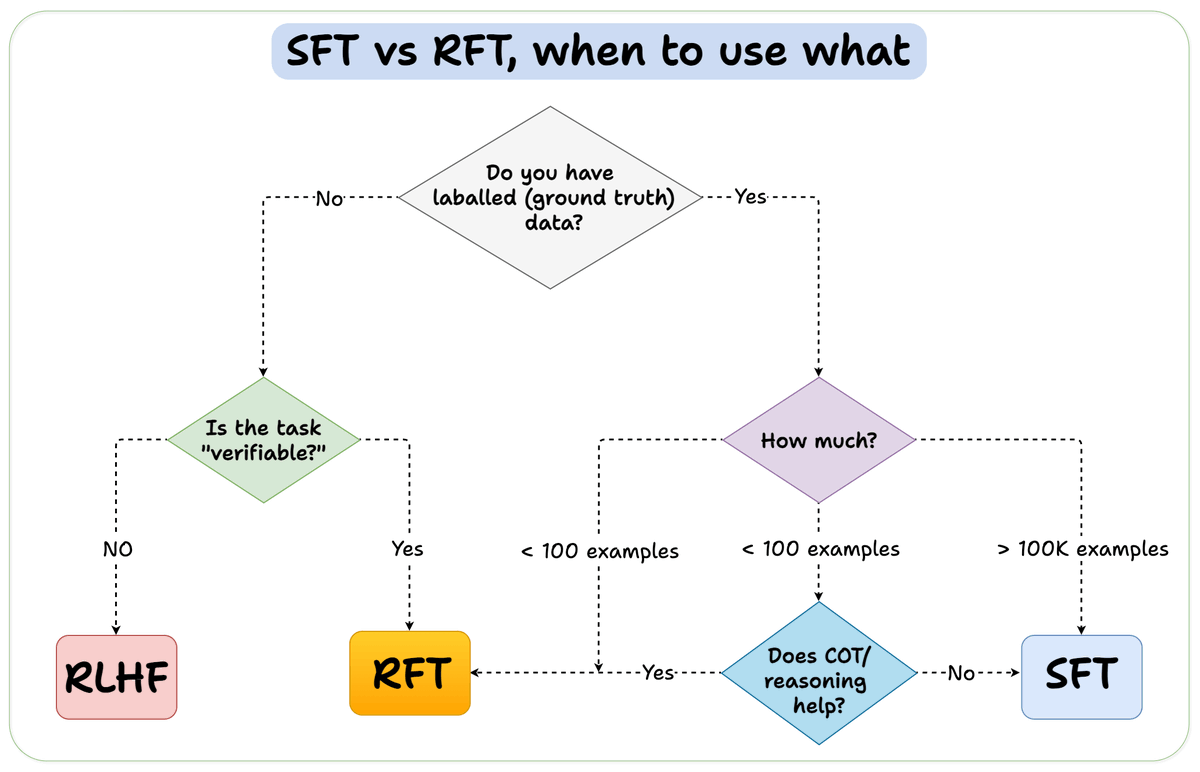
Before we conclude, let me address an important question: When should you use reinforcement fine-tuning (RFT) versus supervised fine-tuning (SFT)? I created this diagram to provide an answer:
Finally, I'll leave you with an overview of the GRPO process. Let me know what other techniques you have used in the comments! You can find all the code and everything you need on the @LightningAI⚡️Studio here: https://lightning.ai/lightning...
That's a wrap! If you found it insightful, reshare with your network. Find me → @akshay_pachaar ✔️ For more insights and tutorials on LLMs, AI Agents, and Machine Learning!