
feeling frustrated (and a little guilty): there’s still way too much confusion about @OpenAI's Responses API. this is partly on us: we haven’t always been clear about why we built it, how to use it, and why it matters. here's my attempt at setting the record straight. 👇
one founder's explanation for why they hadn't switched over to responses yet: we want fine-grained control over our agentic processes – we handle context construction and prompt caching optimization ourselves the reality? this is all possible with responses!
myth #1: it's not possible to do some things with responses nope. responses is a superset of completions. anything you can do with completions, you can do with responses – plus more. for example, you can manage the conversation state manually (like in completions) OR let the


myth #2: responses always keeps state, so we can’t use it in strict Zero Data Retention (ZDR) setups wrong. you can run responses in a stateless way. just ask it to return encrypted reasoning items, and continue handling state client-side as shown above.
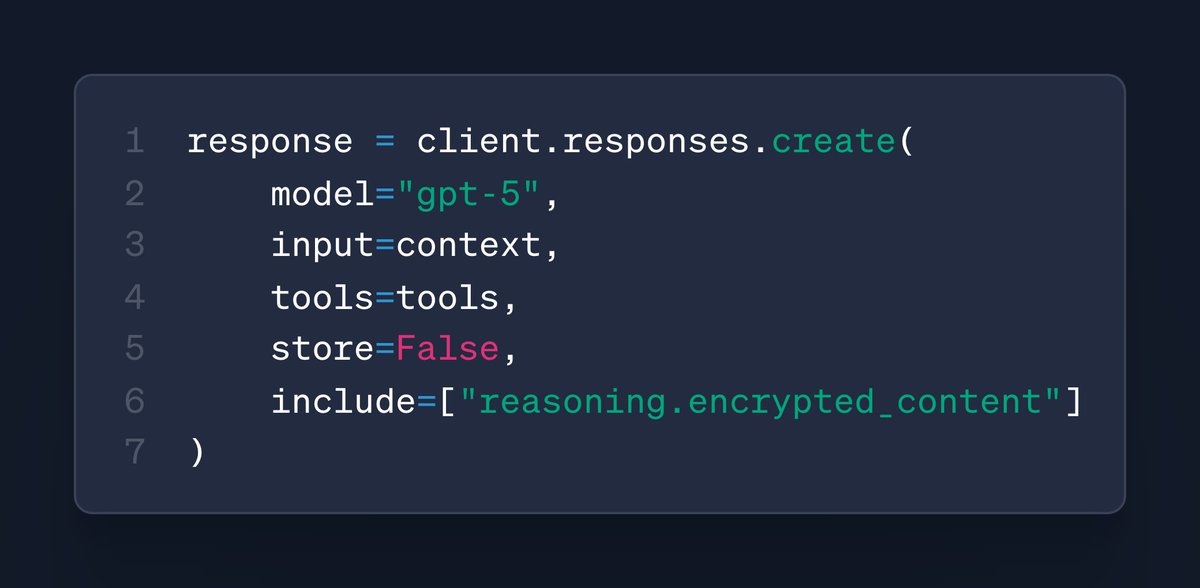
myth #3: model intelligence is the same regardless of whether you use completions or responses wrong again. responses was built for thinking models that call tools within their chain-of-thought (CoT). responses allows persisting the CoT between model invocations when calling
in summary: - responses = completions ++ - works in stateless & ZDR contexts - built for thinking models - unlocks higher intelligence and maximizes cache utilization in agent loops if you’re still on chat completions, consider switching now -- you are likely leaving
@prashantmital @OpenAI We use RAG to answer a user's question. If RAG does not have the info then we want the API to ask user permission to search on web. If the user grants permission, we want to record it and then provide the result from web search. How to do that using Responses API?
@cagefreesingh @OpenAI Are you using an MCP to run the web search? If so, we have a requires_approval parameter that you can use to seek confirmation before firing off the web search query. If you’re using our built-in web search, you will need to get a bit fancier when implementing the approval flow
@prashantmital @OpenAI It's crazy to frame this as: CLAIM -> "wrong", right after a mea culpa.
@llm_wizard @OpenAI lol 😂 fair
@prashantmital @OpenAI Using cot to describe multiple inference turns is confusing when the industry generally used cot to refer to the reasoning tokens produced at an individual inference step
@BrettBaronR32 @OpenAI Indeed! I hope this post https://x.com/prashantmital/st... helps clarify things a bit? Resumability within turns (ie take multiple steps for a model turn) is key to building agents regardless of model, so I agree we would all benefit from agreed upon standard definitions for cot, turn,
@prashantmital @OpenAI The bigger problem is that the got 5 rollout on the responses API was riddled with bugs and undocumented edge cases For example, it is no longer possible to use built-in tools when using tool_choice=required. Why? The complicated linking of reasoning items to subsequent items
@prashantmital @OpenAI You forgot the core issue! The broad compatibility of the completion API. Before you could just switch to a local model or other provider. You first build a standard, slowly everyone adopts and now you go “naaaa … do this instead” instead of making a backward compatible v2.
@prashantmital @OpenAI Hi Prashant, I currently maintain Rig which is the leading AI agent framework in Rust. Supporting the Responses API has been quite tricky because of how many undocumented subtle behaviours that we found manually (for example, why does every single object in a schema need
@prashantmital @OpenAI Just ass a simple sessionID to chat completions so that you can load up CoT on the server, it is much easier solution than forcing us to new API.
@prashantmital @OpenAI Thanks for the writeup. BTW, code-gen tools are also to blame -- they keep picking up Completions API over Responses.
@prashantmital @OpenAI it was so hard for me personally to understand responses and conversations api that i had perplexity use gpt 5 to collect all relevent documentation and examples for me, then i pasted it into gpt 5 thinking with what i wanted to build and had it code it for me
@prashantmital @OpenAI Dude, litellm doesn't support responses api + fastest response batch streaming. I tried switching and wasted my time because it's impossible to rely on open ai alone as a production llm provider.
@prashantmital @OpenAI Jesus this one hit a nerve i see. Simple feedback would be to not conflate two products. 1- Raw token intelligence 2- Hosted orchestration. You risk losing 1 because of 2. Response is very good but closer related to assistant/agent sdk than completion imo. Completion won the
@prashantmital @OpenAI First make the models like GPT-5 completely understand the response API as it will help a lot migrating a entire system from completion to response
@prashantmital @OpenAI It would have been much better for everybody had you given the reasoning tokens that we pay to produce , to us and “we” decide what to do with our tokens. (Perhaps do some other improvements based on them)
@prashantmital @OpenAI Maybe quit blocking bots from accessing your docs page if you want to push a competing standard.
@prashantmital @OpenAI honest Q: is there any advantage to deferring to responses API to retain the context instead of just including everything in a new completions call each time?
@prashantmital @OpenAI Clear communication is key. There's a gap between intention and implementation here. Users need solid docs and examples, not just promises.
@prashantmital @OpenAI When using previous_response_id this comes up a lot: I encountered an error processing your message. Please try again.: 400 Item <id> of type 'reasoning' was provided without its required following item. Super frustrating
@prashantmital @OpenAI People won’t switch because they want the flexibility between models and this API is two different to every other model provider Like we use open router as a mechanism to use your models and everyone else’s models because it’s the easiest way to switch between everything so we
@prashantmital @OpenAI I turned on reasoning summaries and they were not visible in the dashboard. Is there any cookbook or prompting guide to debug this? Is it a bug? Related: https://community.openai.com/t...
@prashantmital @OpenAI A proxy that’ll allow backward compatibility would go a long way
@prashantmital @OpenAI Thanks for the info. I think one reason for not switching is many providers offer OpenAI compatibility via the chat completions API that was standard for some time. There is friction in switching to something that is new and not as standard. Is responses API format becoming
@prashantmital @OpenAI Thanks Prashant, can you convert this to a .md file I can stick in Codex CLI instructions - it’s super useful information for codex to know when we’re making apps that call OAI models
@prashantmital @OpenAI Reality: teams want optionality and would rather use a standard API than learn a new one specific to OpenAI
@prashantmital @OpenAI You should really create md versions of your docs. A lot of people are using AI agents to code that don’t really know about the responses API. See the case of @elevenlabsio, they do this within their docs pages
@prashantmital @OpenAI OpenAi keeps changing standards, while other platforms try to offer OpenAI compatibility.