
🚨 NVIDIA just did the impossible. They trained a 12B-parameter language model on 10 trillion tokens entirely in 4-bit precision. It’s called NVFP4, and it might redefine how frontier AI models are trained. Here’s why this matters: • NVFP4 delivers 2–3× faster math

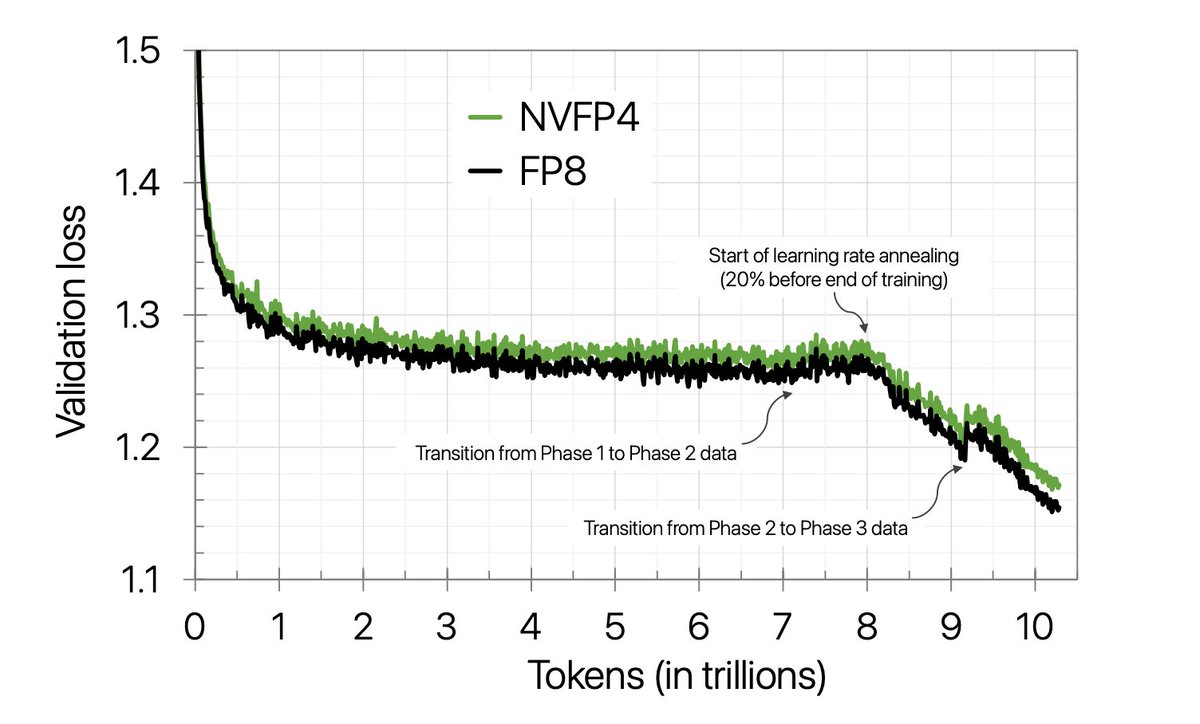
The wild part? NVFP4 tracks FP8 almost perfectly across 10 trillion tokens of training. The validation loss curve (below) shows <1% difference for most of training widening only slightly as learning rate decays. That’s 4-bit training behaving like 8-bit 🤯
Accuracy didn’t budge. Across MMLU, GSM8K, MATH, and coding benchmarks NVFP4 nearly mirrors FP8. Even in long-context math & reasoning, it holds strong. One stat says it all: MMLU-Pro (5-shot): 62.58% vs 62.62%.

How did they make 4-bit stable? 4 key tricks kept NVFP4 from collapsing: 1. Random Hadamard Transforms 2. 2D block scaling 3. Stochastic rounding on gradients 4. Selective high-precision layers Remove any one and training diverges.

Here’s what 4-bit pretraining actually looks like under the hood 👇 Every GEMM (matrix multiply) runs in NVFP4. Only the final 10–15% of layers stay in BF16 for stability. Gradients get stochastic rounding for unbiased updates. This figure says it all a full 4-bit pipeline

They even compared it to MXFP4 the older 4-bit format. Result? NVFP4 reaches the same loss 36% faster. MXFP4 needs 1.36T tokens to catch up with NVFP4’s 1T. That’s a one-third reduction in training time. 4-bit isn’t just possible. It’s now efficient. Read the full paper

@godofprompt 4-bit used to be a compression trick. Now it’s core infrastructure. Insane progress.
@heyrimsha it's insane
@godofprompt The 2D block scaling + stochastic rounding combo is underappreciated. Feels like the unsung hero here.
@nextool_ai yeah
@godofprompt The paper is great, but the implications are better. This sets the standard for what future efficiency looks like in LLMs.
@rryssf_ yeah
@godofprompt Interesting that depth of layers turns out to be more important that precision
@godofprompt This could be a turning point for startups building custom LLMs. Dropping compute costs without sacrificing performance changes the equation entirely.
@godofprompt 4-bit wins are huge, but quantization can shift calibration and edge-case behavior. Run OOD evals, jailbreak tests, and cost caps before rolling to prod. Faster ≠ safer by default.
@godofprompt Damn I still didn’t convert my models to fp8 😭
@godofprompt while impressive, NVIDIA’s NVFP4 results warrant skepticism until independent benchmarks confirm that 4 bit precision truly maintains accuracy and stability at such unprecedented scale.
@godofprompt @PrestonPysh 🎯 it will be the architecture 👍♾️
@godofprompt The key point is the full life cycle becomes 4 bit. Traditionally models are trained at 16 bit and later compressed to 4. That reduces serving costs but not training costs. This cuts training by 6x because the Nvidia Blackwell generation has 4 bit hardware acceleration.
@godofprompt NVFP4 is a massive leap — true 4-bit training at scale without accuracy loss changes everything. Faster, cheaper, and greener AI is officially here.
@godofprompt The fact that they maintained accuracy across 10T tokens with NVFP4 is wild. No trade-offs, just better efficiency.
@godofprompt Efficiency leap unlocks faster progress, democratizing access to powerful AI models.
@godofprompt NVIDIA’s NVFP4 trains huge AI faster & greener
@godofprompt 4-bit training at that scale is wild… speed gains alone could change how fast new ideas hit production.
@godofprompt Impressive result, but it’s not pure 4-bit everywhere — they still rely on selective high-precision layers, complex stability tricks, and Blackwell hardware. It works well on a 12B model, but how general or practical this is at larger scales remains an open question.
@godofprompt Nvidia is going insane
@godofprompt This breakthrough could truly accelerate AI development and make large-scale models more accessible. It'll be exciting to see how this impacts future innovations.
@godofprompt Win-win for everyone 🙌