
bro @karpathy literally re-implemented the entire lm-eval-harness in 2 Python files It's been very useful for my own repo and easy to adapt for SuperBPE case
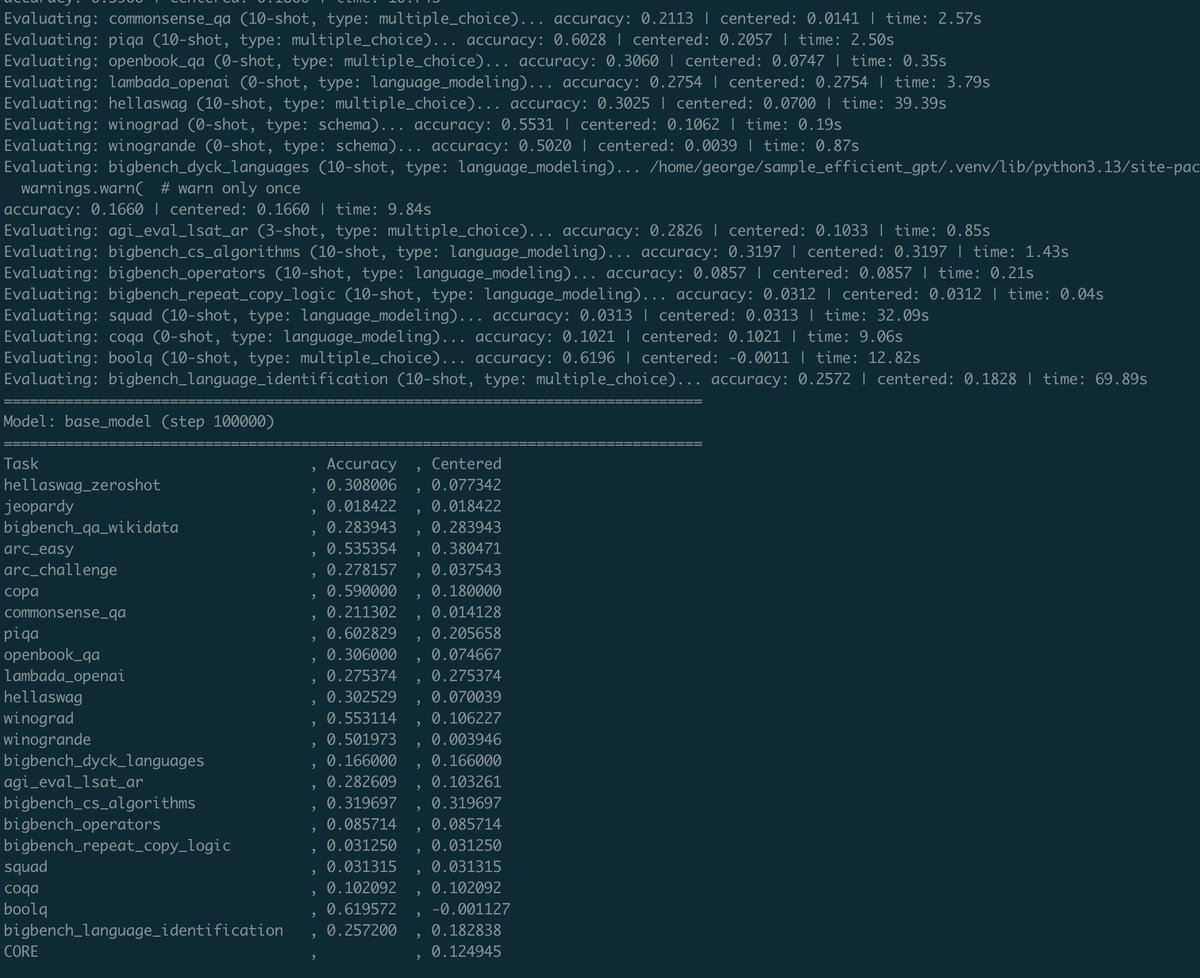
@iamgrigorev Thank you! I'm quite happy with the core_eval.py rewrite. I wanted to evaluate my base model with the DCLM "core score" as described in their paper, but what felt like it should surely be a simple thing of ~300 lines of code actually required me to pip install and depend on a
@karpathy @iamgrigorev it's very clean tbh make me realize i might just do the same instead of relying on existing lib for pre-training evals
@eliebakouch @karpathy definitely worth it! or just take from nanochat. I just changed the way model is loaded and forward pass, tweaked some tokenization and batching functions and it just works now. (oh and modernized to use pathlib)
@karpathy yea, i liked that you manually converted all benchmarks into "your" format so that it's simple to ingest using just yaml
@karpathy @iamgrigorev All done by hand or LLM?
@karpathy @iamgrigorev Yeah I don't think we would describe the llm-foundry eval harness as the "cleanest" way to get the score. It was designed around getting really fast eval results during training with models already loaded into FSDP in a distributed multi-node setting. very cool!
@karpathy @iamgrigorev unrelated, but can you please leave a prompt/eval to test grok 5 based on your researching capabilities? Bless the timeline with ammo for whenever grok 5 may release.
@karpathy @iamgrigorev After watching your conversation with @dwarkesh_sp today, I walked away thinking your (AI) heart is at the right place.
@karpathy @iamgrigorev AI-based slimming of Python projects could be a standardizable step. - Problem description: Layered dependencies based on Python packages lead to projects being overly large, unclear code, inability to effectively debug, and many other issues. - Solution: User-unaware, complete
@karpathy @iamgrigorev You're the real AGI
@karpathy @iamgrigorev pip addiction is real, fr
@karpathy @iamgrigorev feels like a dependency rabbit hole
@karpathy @iamgrigorev based library stack, fr/fr
@karpathy @iamgrigorev I need to get a @
@karpathy @iamgrigorev So lm-eval is still useful when evaluating post-trained LLMs :)
@karpathy @iamgrigorev sounds like classic pip adventures
@karpathy @iamgrigorev real build hours
@karpathy @iamgrigorev Need to get a @karpathy t-shirt. Thanks for being transparent and professional about the real state of AI. Much respect